Open Source · JUN 24, 2026 · 7 MIN READ
ARD: A Domain-Anchored Protocol for Discovering Agentic Resources
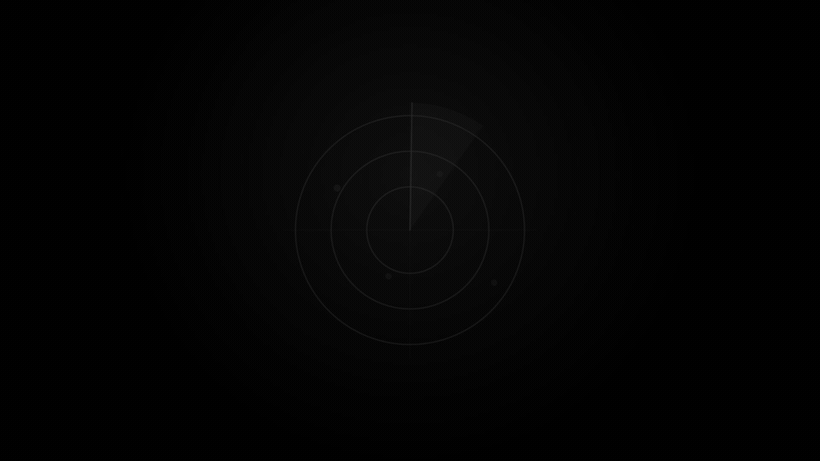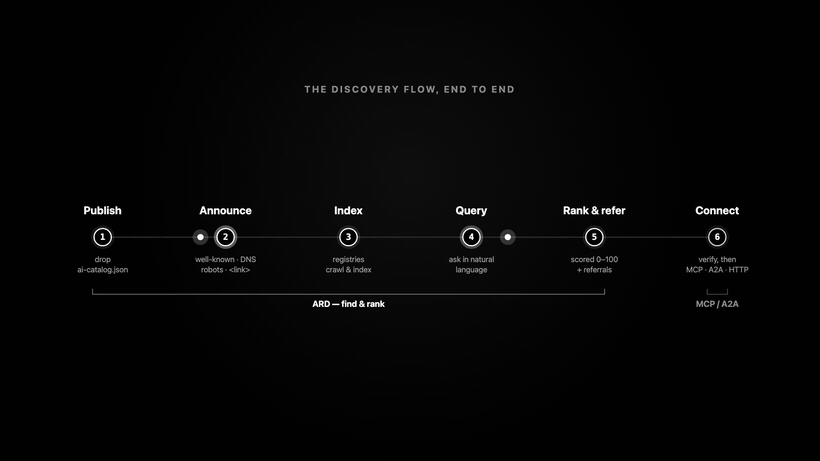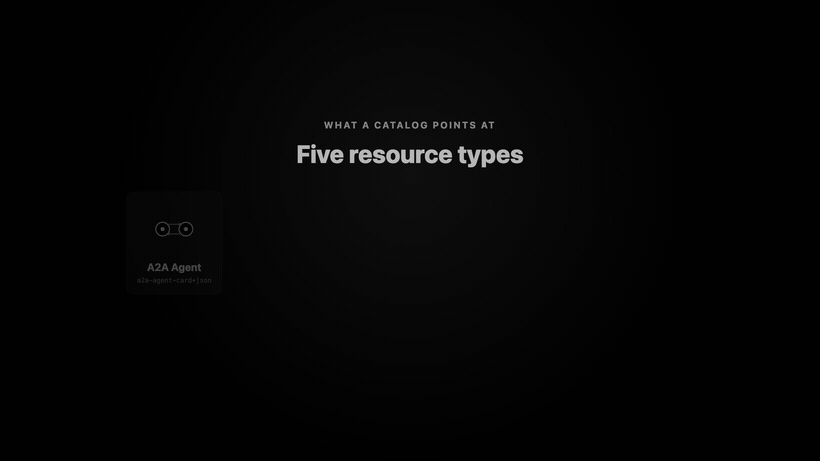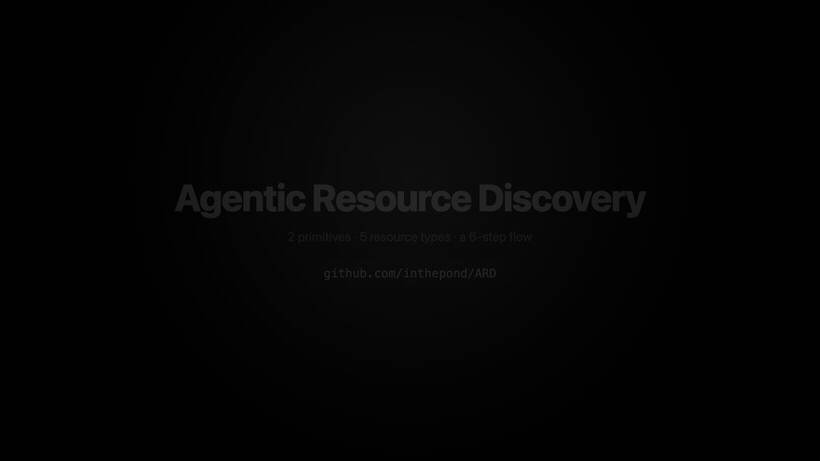
An agent that wants to do real work needs three answers it cannot get today: where does the right capability live, which one should it actually use, and how does it know that capability is safe to connect to? We have good protocols for using a capability once you have its address — MCP for tools and context, A2A for agent-to-agent calls, plain HTTP for APIs — but nothing for finding those capabilities across organizational boundaries. Agentic Resource Discovery (ARD) is the proposed answer: a federated, domain-anchored protocol for publishing, searching, and trusting agentic resources across the open web. We published an opinionated companion to the specification.
Two Primitives: Catalogs and Registries
ARD is built from exactly two things. A Catalog is a static JSON file an organization publishes under its own domain, at the well-known path /.well-known/ai-catalog.json. It lists the resources that organization offers, and it is dumb on purpose — no query logic, just a manifest. A Registry is a searchable service that crawls many catalogs and indexes them, so a client can ask a natural-language question and get back ranked, relevant resources. Crucially there is no one registry: registries federate, referring queries to each other, so no single operator becomes the gatekeeper of discovery. Publishing is decentralized and free; searching is a service someone has to run — the same shape as websites versus search engines.
The Domain Is the Root of Trust
ARD's identity story starts from a single move: the catalog lives on a domain, and control of that domain is the root of trust. If you fetched the catalog over a valid TLS connection, the web's PKI already vouches that you are talking to whoever holds that domain — no new registry-of-record has to be minted. On top of that, an optional trustManifest carries stronger claims: a cryptographic identity (a SPIFFE ID, a DID, or an HTTPS URI), attestations like SOC2-Type2 or HIPAA pointing at evidence by URI, provenance, and an optional JWS signature. The binding rule is the load-bearing part: the publisher segment of an entry's URN must align with the cryptographic authority in the identity. You cannot publish urn:air:acme.com from a manifest whose identity resolves to evil.example.
Entries Point at Native Cards — They Do Not Replace Them
Each entry in a catalog has a domain-anchored URN identifier, a display name, and an IANA-style media type that tells a client what protocol the resource speaks. The pattern to notice is that ARD does not invent a description format for agents or tools — it references the native card formats and just indexes them. The catalog is glue, not a replacement.
| Media type | Resource it points at |
|---|---|
| application/a2a-agent-card+json | An A2A protocol agent (an Agent Card) |
| application/mcp-server-card+json | An MCP server |
| application/ai-catalog+json | A nested catalog — catalogs can bundle catalogs |
| application/ai-registry+json | A registry search endpoint |
| application/ai-skill | A generic skill artifact |
The Search Layer, and One Sharp Guardrail
A registry exposes an HTTP API over everything it has crawled: POST /search takes a natural-language query and returns ranked results each with a 0–100 relevance score, POST /explore returns faceted aggregations to understand the space, and GET /agents gives deterministic, paginated browsing. Federation is a query-time choice — auto follows referrals across registries, referrals returns them without following, none answers only from the local index. One guardrail is stated emphatically: score is semantic relevance only, and MUST NOT be interpreted as a trust, compliance, or safety rating. "Most relevant" is not "most trustworthy." Keeping those two axes separate is one of ARD's better instincts.
Where ARD Sits: Complementary, Not Competitive
MCP, A2A, and ARD get lumped together as "agent protocols," which hides that they operate at different layers. MCP answers how a client uses a tool once it has the address. A2A answers how two agents talk. ARD answers how you find an MCP server or A2A agent across the web and decide which to trust — it is DNS plus a search engine plus the TLS trust anchor. MCP and A2A assume you already know where the capability is; ARD is the layer above both, the missing front door. The tell is in ARD's own type registry, which has first-class media types for MCP and A2A cards: it indexes them, it does not replace them.
| Protocol | Question it answers | Analogy |
|---|---|---|
| MCP | How does my client use this tool once I have its address? | A device driver / a DB connection |
| A2A | How do two autonomous agents talk to each other? | An RPC between services |
| ARD | How do I find a resource across the web, and trust it? | DNS + a search engine + TLS |
What Is Strong, What Is Still Soft
The companion keeps spec facts and opinion separate on purpose. The genuinely strong calls: reusing the web's PKI instead of inventing a central authority, federation over centralization, native-format pass-through, and the explicit refusal to let a search rank masquerade as a safety signal. What is still soft: signatures are optional, so default trust is only "served over TLS from this domain" — that proves origin, not that a claimed SOC2 badge is real; the registry ranking is an unspecified black box and an attack surface for catalog spam; capability semantics are free text with no shared ontology; and it is a v0.9 draft, so pin versions and expect churn. ARD nails the identity of the publisher and leaves softer the integrity of the claims and of the index. Those are the seams to watch.
Publish a Catalog in Five Minutes
The whole barrier to entry is a domain and the ability to serve a static file — which is the point. Write the manifest, serve it over valid TLS at the well-known path, make sure every URN publisher segment matches the domain, announce it so crawlers find it, and validate against the official JSON Schema before shipping.
{
  "specVersion": "1.0",
  "host": { "displayName": "Acme Corp", "identifier": "acme.com" },
  "entries": [
    {
      "identifier": "urn:air:acme.com:mcp:invoices",
      "displayName": "Invoice Tools",
      "type": "application/mcp-server-card+json",
      "url": "https://mcp.acme.com/.well-known/mcp-server-card.json",
      "representativeQueries": ["reconcile this month's invoices"],
      "trustManifest": { "identity": "https://acme.com", "identityType": "https" }
    }
  ]
}
Serve that at https://acme.com/.well-known/ai-catalog.json and you have a published, discoverable, domain-anchored capability. A registry can crawl it, and any agent can find it. The companion distills sections 1–6 of the v0.9 draft faithfully and keeps sections 7–9 as clearly labelled opinion; it is independent of, and not affiliated with, the ARD specification.
this note evidences a capability — AI-Native Solutions ↓